 Roman Klimenko
Exporting data from CluedIn to Databricks or Microsoft Fabric
In this article, we'll load data from CluedIn into a Databricks notebook, explore and transform it, and save the result in a Delta Lake table.
CluedIn
Our CluedIn instance has 601,222 entities of type /IMDb/Title.
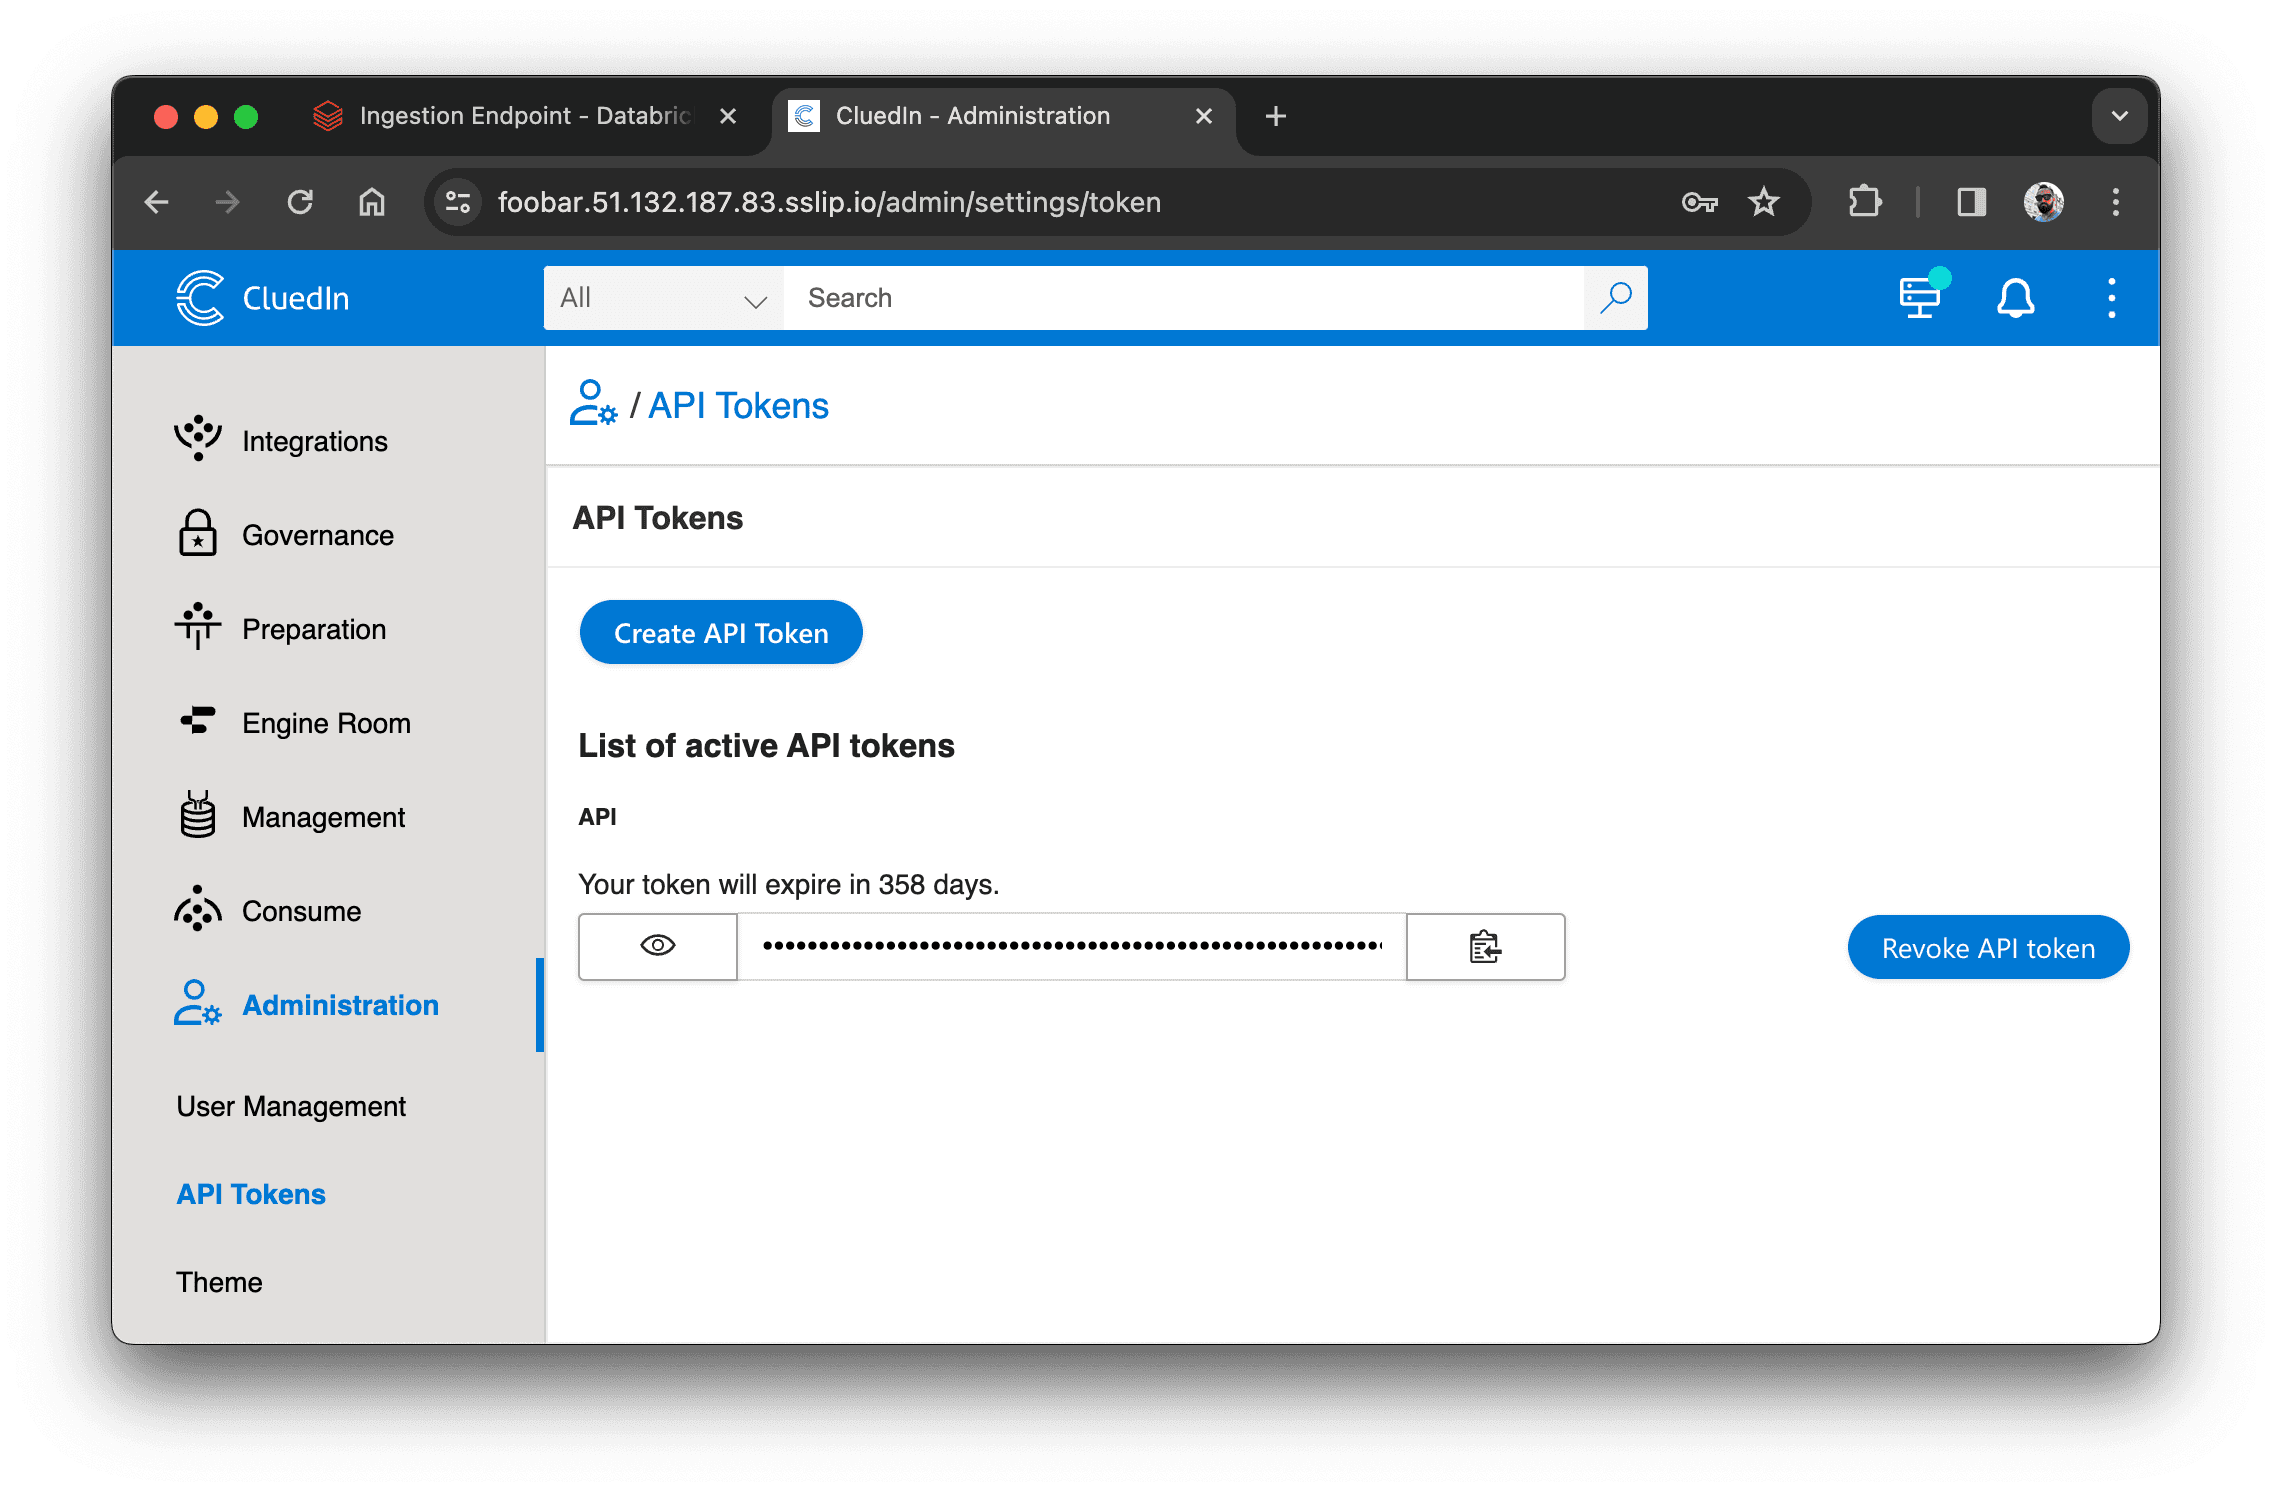
To load them into Databricks, create an API token under Administration > API Tokens in CluedIn:
Databricks
Install dependencies
To connect to the CluedIn API, install the cluedin library:
%pip install cluedin==2.2.0
Import libraries
Import the libraries used in the notebook:
import pandas as pd
import matplotlib.pyplot as plt

import cluedin
Connect to CluedIn
To connect to CluedIn, provide the instance URL and the API token created earlier:
# CluedIn URL: https://foobar.mycluedin.com/:
#   - foobar is the organization's name
#   - mycluedin.com is the domain name

cluedin_context = {
  'domain': 'mycluedin.com',
  'org_name': 'foobar',
  'access_token': '(your token)'
}
Fetch one row first to inspect the data:
# Create a CluedIn context object.
ctx = cluedin.Context.from_dict(cluedin_context)

# GraphQL query to pull data from CluedIn.
query = """
query searchEntities($cursor: PagingCursor, $query: String, $pageSize: Int) {
  search(
    query: $query
    cursor: $cursor
    pageSize: $pageSize
    sort: FIELDS
    sortFields: {field: "id", direction: ASCENDING}
  ) {
    totalResults
    cursor
    entries {
      id
      name
      entityType
      properties
    }
  }
}
"""

# Fetch the first record from the `cluedin.gql.entries` generator.
next(cluedin.gql.entries(ctx, query, { 'query': 'entityType:/IMDb/Title', 'pageSize': 1 }))
Output:
{'id': '00001e32-9bae-53b9-a30f-cf30ed66c360',
 'name': 'Murder, Money and a Dog',
 'entityType': '/IMDb/Title',
 'properties': {'attribute-type': '/Metadata/KeyValue',
  'property-imdb.title.endYear': '\\N',
  'property-imdb.title.genres': 'Comedy,Drama,Thriller',
  'property-imdb.title.isAdult': '0',
  'property-imdb.title.originalTitle': 'Murder, Money and a Dog',
  'property-imdb.title.primaryTitle': 'Murder, Money and a Dog',
  'property-imdb.title.runtimeMinutes': '65',
  'property-imdb.title.startYear': '2010',
  'property-imdb.title.tconst': 'tt1664719',
  'property-imdb.title.titleType': 'movie'}}
For consistent pagination and better performance, sort the GraphQL results by a unique field. The entity ID works well:
    sort: FIELDS
    sortFields: {field: "id", direction: ASCENDING}
Now load the full dataset into a Pandas DataFrame. The helper below flattens the properties, removes unnecessary prefixes, and replaces dots with underscores to make the names compatible with the Spark schema:
ctx = cluedin.Context.from_dict(cluedin_context)

query = """
query searchEntities($cursor: PagingCursor, $query: String, $pageSize: Int) {
  search(
    query: $query
    sort: FIELDS
    cursor: $cursor
    pageSize: $pageSize
    sortFields: {field: "id", direction: ASCENDING}
  ) {
    totalResults
    cursor
    entries {
      id
      properties
    }
  }
}
"""

def flatten_properties(d):
    for k, v in d['properties'].items():
        if k == 'attribute-type':
            continue

        if k.startswith('property-'):
            k = k[9:] # len('property-') == 9

        k = k.replace('.', '_')

        d[k] = v

    del d['properties']

    return d

df_titles = pd.DataFrame(
    map(
        flatten_properties,
        cluedin.gql.entries(ctx, query, { 'query': 'entityType:/IMDb/Title', 'pageSize': 10_000 })))

df_titles.head()

Set the DataFrame's index to the entity ID:
df_titles.set_index('id', inplace=True)
df_titles.head()

Explore data
Let's see how many movies we have by genre:
df_titles['imdb_title_genres'].str.split(',', expand=True).stack().value_counts().plot(kind='bar')
plt.title('Distribution of genres')
plt.xlabel('Genres')
plt.ylabel('Count')
plt.show()

Create schema
Now create a schema for the data.
The imdb_title_genres value is a string rather than an array, so split it first:
from pyspark.sql import SparkSession
from pyspark.sql.types import StructType,StructField, StringType, ArrayType, IntegerType
from pyspark.sql.functions import split

spark = SparkSession.builder.getOrCreate()

schema = StructType([
    StructField('id', StringType(), True),
    StructField('imdb_title_endYear', StringType(), True),
    StructField('imdb_title_genres', ArrayType(StringType()), True),
    StructField('imdb_title_isAdult', StringType(), True),
    StructField('imdb_title_originalTitle', StringType(), True),
    StructField('imdb_title_primaryTitle', StringType(), True),
    StructField('imdb_title_runtimeMinutes', StringType(), True),
    StructField('imdb_title_startYear', StringType(), True),
    StructField('imdb_title_tconst', StringType(), True),
    StructField('imdb_title_titleType', StringType(), True)
    ])

df_spark_titles = spark.createDataFrame(df_titles)

df_spark_titles = df_spark_titles.withColumn('imdb_title_genres', split(df_spark_titles.imdb_title_genres, ','))

spark.sql('CREATE DATABASE IF NOT EXISTS cluedin')

df_spark_titles.write.mode('overwrite').format('parquet').saveAsTable('cluedin.imdb_titles', schema=schema)
display(df_spark_titles)
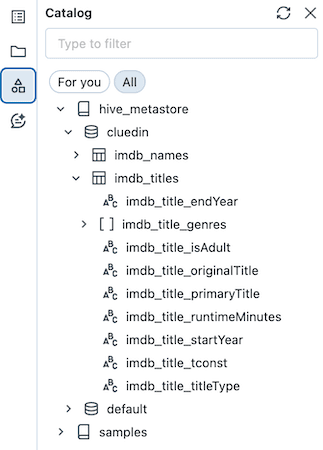
The data is now available in the catalog: